
TL;DR
Thorsten Meyer AI has published a capstone comparison of Apple Silicon Macs and GPU towers for local LLM use. The piece says towers win on speed when models fit in VRAM, while high-memory Macs can run larger models with far less heat and noise at the desk.
Thorsten Meyer AI has published a capstone comparison of Apple Silicon Macs and GPU towers for local LLM work, arguing that the practical choice depends on memory bandwidth, memory capacity, heat and noise. The guide matters for readers choosing local AI hardware because it frames the tradeoff between faster token generation on models that fit GPU VRAM and quieter operation with larger unified memory on high-end Macs.

Get business pricing on tech for your team
- Business-only prices and quantity discounts
- Tax-exempt purchasing
- Multiple users, one account, clear invoices
The article positions the comparison as the final piece in a series on reducing heat and noise in high-power AI workstations. It says the key buying question is whether a user’s main limit is throughput on models that fit inside VRAM or the ability to load larger quantized models that exceed a consumer GPU’s memory.
According to the guide, an RTX 5090-class tower is built around bandwidth, citing roughly 1,792 GB/s of memory bandwidth and 24GB to 32GB of VRAM per consumer card. It says a Mac Studio M3 Ultra targets capacity, citing about 819 GB/s of memory bandwidth and unified memory configurations up to 256GB to 512GB that can be allocated to a single inference job.
The source says the tower can deliver several times more tokens per second on Q4_K_M quantized models that fit in VRAM, while the Mac may run 70B or larger quantized models that a single consumer GPU cannot hold. It also says token rates vary by model, quantization and workload, and that the page includes affiliate links and live pricing.
Why It Matters
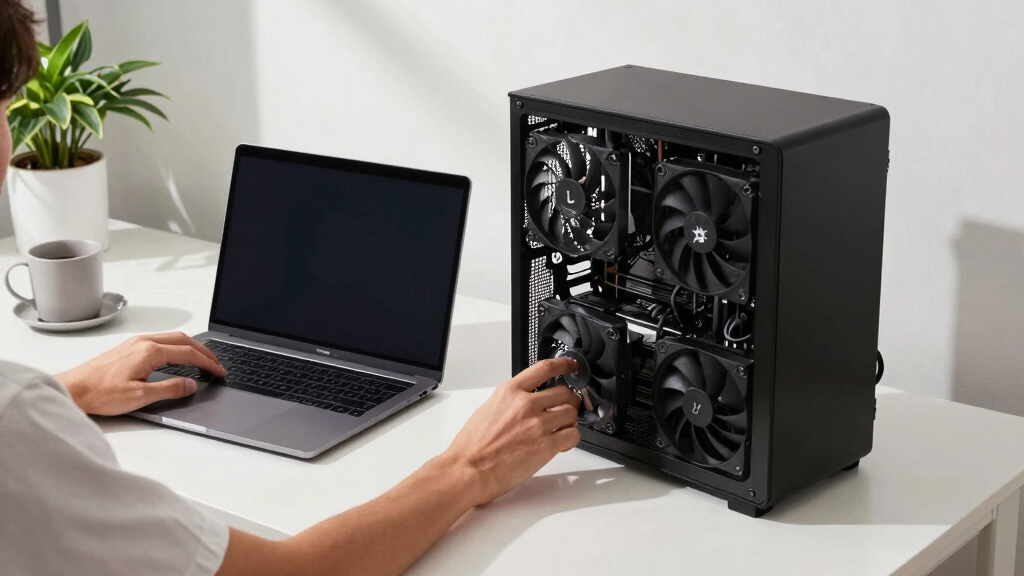
The comparison is aimed at readers deciding whether local AI work should live on a desk, in another room or across both systems. A tower may be the stronger fit for CUDA workloads, fine-tuning and repeated throughput jobs, but the article says that performance brings fan, airflow, cooler, undervolting and placement decisions.
A Mac may reduce desk heat and sound because Apple Silicon uses a shared memory design and lower power draw, according to the guide. The tradeoff is slower per-token performance and a different software stack, which can matter for users whose workflows depend on NVIDIA GPUs or CUDA.
Products Worth Considering

Apple MacBook Air 15-inch (2026) with M5 chip, 16GB memory, 512GB SSD — Midnight

Apple AirPods Pro 3 Wireless Earbuds with Active Noise Cancellation
Bose QuietComfort Ultra Earbuds (2nd Gen), Wireless Noise-Cancelling Earbuds, Black
As an affiliate, we earn on qualifying purchases.
Background
The article builds on earlier Thorsten Meyer AI coverage about undervolting, cooler choice, case airflow, fan tuning and workstation placement. This piece changes the frame from quieting a GPU tower to asking whether some users should avoid the heat and noise problem by choosing Apple Silicon instead.
The guide states that VRAM on multiple consumer GPUs does not simply combine into one larger pool for a single model. That matters because a dual-GPU tower may raise throughput and power draw, while still failing to load a model that exceeds the usable memory of one card, depending on the software and model setup.
“A GPU tower is a high-bandwidth furnace you spend five levers learning to quiet.”
— Thorsten Meyer AI guide
“Apple Silicon is near-silent by design – but asks you to accept a different set of tradeoffs.”
— Thorsten Meyer AI guide
“Silence is its default, not an achievement.”
— Thorsten Meyer AI guide
What Remains Unclear
The exact performance gap remains workload-dependent. The article describes token rates as ballpark figures for Q4_K_M quantized models, and says results vary by model, quantization and workload.
The supplied material cites 2026 comparisons, independent benchmarks and datasheets, but does not include the full benchmark table, acoustic measurements, room conditions or detailed tower configuration. Actual heat and noise will depend on case design, cooling hardware, fan curves, ambient temperature and where the machine is placed.
What’s Next
The guide points readers toward matching hardware to workload rather than treating Mac versus tower as a single winner-take-all choice. For mixed use, it describes a hybrid setup: a quiet Mac at the desk for interactive work and large-memory inference, with a headless GPU tower in another room for throughput jobs, fine-tuning and CUDA tasks accessed over SSH.
The next useful milestone for buyers would be side-by-side tests that publish tokens per second, wall power, acoustics and thermals across the same models and quantization settings.
Key Questions
Is a GPU tower faster for local LLMs?
According to the guide, yes, when the model fits inside GPU VRAM. The source says an RTX 5090-class tower can deliver several times more tokens per second than a Mac Studio M3 Ultra on models that fit.
Can a Mac run larger local models?
The guide says high-end Apple Silicon systems can run larger quantized models because unified memory can reach far beyond the VRAM available on a single consumer GPU. It cites 70B or larger models as cases where capacity can matter more than speed.
Why are heat and noise central to this comparison?
The source says a single RTX 5090 draws about 575W and a dual-GPU rig can pass 800W, with most of that power becoming heat. A Mac draws far less power for many local inference tasks, which can make it easier to keep at a desk.
Does the article declare one clear winner?
No. It says the answer depends on whether the user values speed on models that fit VRAM, the ability to load larger models, low desk noise, CUDA support or a hybrid setup using both machines.
Source: Thorsten Meyer AI