TL;DR

Get tech for your team delivered free — and shop member deals
- Fast, free delivery on millions of items
- Access to Prime Big Deal Days deals on October 6–7
- Prime Video, Amazon Music and more included
The Strata GitHub project says its software can run the 125-billion-parameter Qwen3.8-Flash-Next model on supported Windows and Linux PCs, using a graphics card with at least 12 GB of VRAM and system RAM. Its published tests report up to 94 tokens per second generating answers on an RTX 5070, not an RTX 4090, and do not substantiate the prompt’s 100-trillion-tokens-per-second figure.
The open-source Strata project says it can run the 125-billion-parameter Qwen3.8-Flash-Next AI model on supported consumer PCs, with its documentation listing graphics cards with at least 12 GB of VRAM. Its published benchmarks report a peak of 94 tokens per second generating answers on an RTX 5070—not an RTX 4090—and provide no evidence for the “100T/s” figure in the topic description; the project’s speed figures are in tokens per second, not trillions of tokens per second.
Strata’s GitHub documentation says the software runs on Windows 10 or 11 and Linux with supported NVIDIA or AMD graphics cards. It describes the model as capable of chat, code writing and image understanding, and says processing can take place locally so that user data does not leave the PC. These are project descriptions; the supplied material does not include an independent security assessment or outside verification of model capabilities.
The project reports tests on two PCs: an RTX 5070 with 12 GB of VRAM, a Ryzen 5 7600 processor and 64 GB of RAM; and an RX 9070 XT with 16 GB, a Ryzen 9 3900X and 47 GB of RAM. On the NVIDIA system, the listed answer-generation results range from 53 to 94 tokens per second across model formats; the AMD results range from 44 to 60 tokens per second. Prompt-processing rates are reported separately, reaching 2,650 tokens per second in one NVIDIA configuration.
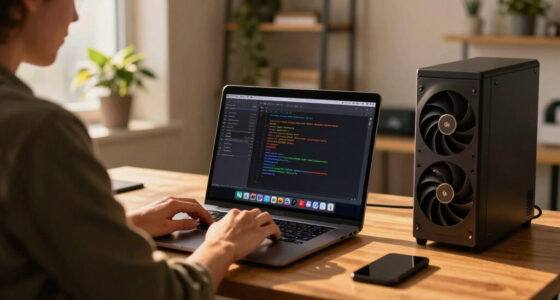
The benchmark notes specify 4,000-token answers and 32,000-token prompts for most NVIDIA rows, while the Q2_0 result used a different engine version. The project says the model download is about 70 GB, and startup loads roughly 35–55 GB into system memory. Its hardware guidance calls for at least 32 GB of RAM and about 80 GB of free disk space, preferably on an SSD. Multiple graphics cards can share the model, according to the documentation.
Local AI on Gaming PCs
If the reported performance is reproducible, Strata could make a large model accessible without relying on a hosted service. Local operation can give users more control over where prompts and files are processed and may be useful when network access is limited. It also lets users connect the model to apps and coding agents, according to the project.
The trade-off is substantial hardware demand. A card with 12 GB of VRAM is listed as the minimum, but the setup also relies on system memory to accommodate the model; performance and the model format depend on available resources. The benchmarks are project-reported results from two specific PCs, not a broad independent test, and they do not establish how well the model will perform across other consumer systems.
As an affiliate, we earn on qualifying purchases.
What the Benchmarks Actually Measure
The source distinguishes between generating an answer and processing an incoming prompt. Those operations have different rates: the reported answer-generation figures are in tokens per second, while prompt processing is measured on a 32,000-token input. A token is approximately three-quarters of a word, according to Strata. The two metrics should not be combined or treated as a single general speed claim.
Strata offers several compressed model formats. Its guidance says smaller formats run faster and require less memory, while larger formats are intended to preserve more quality. For a 64 GB RAM system it recommends IQ2_XS, with IQ3_XXS and IQ3_S as options; the project describes IQ3_S as its best-quality listed choice, but also the slowest among those options. The supplied source says an RTX 3090 with 24 GB of VRAM should reach about 100–140 tokens per second, but presents that as an estimate, not a measured result in the benchmark table.
“Nothing leaves your PC.”
— Strata project documentation
As an affiliate, we earn on qualifying purchases.
RTX 4090 Claim Lacks Test Data
The supplied report does not list an RTX 4090 benchmark, despite the topic’s reference to that card. Nor does it explain what “100T/s” is intended to mean; the documented measurements use tokens per second and are well below 100,000 tokens per second. The figures therefore cannot substantiate a claim of 100 trillion tokens per second.
The source provides no independent replication, full benchmark tables beyond a reference to a details file, or results for every supported graphics card. It also does not give enough information here to compare output quality across formats or verify the privacy claim. Results may vary with hardware, settings, model format and software version.
high performance SSD for AI models
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
More Hardware Tests Needed
Strata points readers to its repository’s full benchmark details and installation documentation for additional configurations and setup options. The project says users can run its installer to detect hardware and select a model format. Independent tests on an RTX 4090 and other common consumer cards would clarify how broadly the published performance figures apply and whether the topic’s speed claim refers to a different metric.
Until such results are available, the clearest supported takeaway is that Strata reports running the model on the specified RTX 5070 and AMD systems—not that an RTX 4090 achieves 100T/s. The project’s documentation may change as software and drivers are updated.
As an affiliate, we earn on qualifying purchases.
Key Questions
Does the source show Qwen3.8-Flash-Next running on an RTX 4090?
No. The benchmark systems listed are an RTX 5070 and an AMD RX 9070 XT. The supplied material does not report an RTX 4090 test.
What speed does Strata report?
Its RTX 5070 results list 53–94 tokens per second for answer generation, depending on model format. The AMD results range from 44 to 60 tokens per second. These are project-reported measurements, not independent tests.
What hardware does Strata list as a minimum?
The documentation calls for a supported NVIDIA or AMD graphics card with at least 12 GB of VRAM, at least 32 GB of system RAM and about 80 GB of free disk space. Actual performance depends on the system and model format.
Does “100T/s” mean 100 trillion tokens per second?
The source does not define that shorthand and gives its benchmarks in tokens per second. It does not report or support a speed of 100 trillion tokens per second.
Source: hn
Halloween Picks
halloween
As an affiliate, we earn on qualifying purchases.