

Get business pricing on tech for your team
- Business-only prices and quantity discounts
- Tax-exempt purchasing
- Multiple users, one account, clear invoices
Authors allege their books were pirated and used in AI datasets
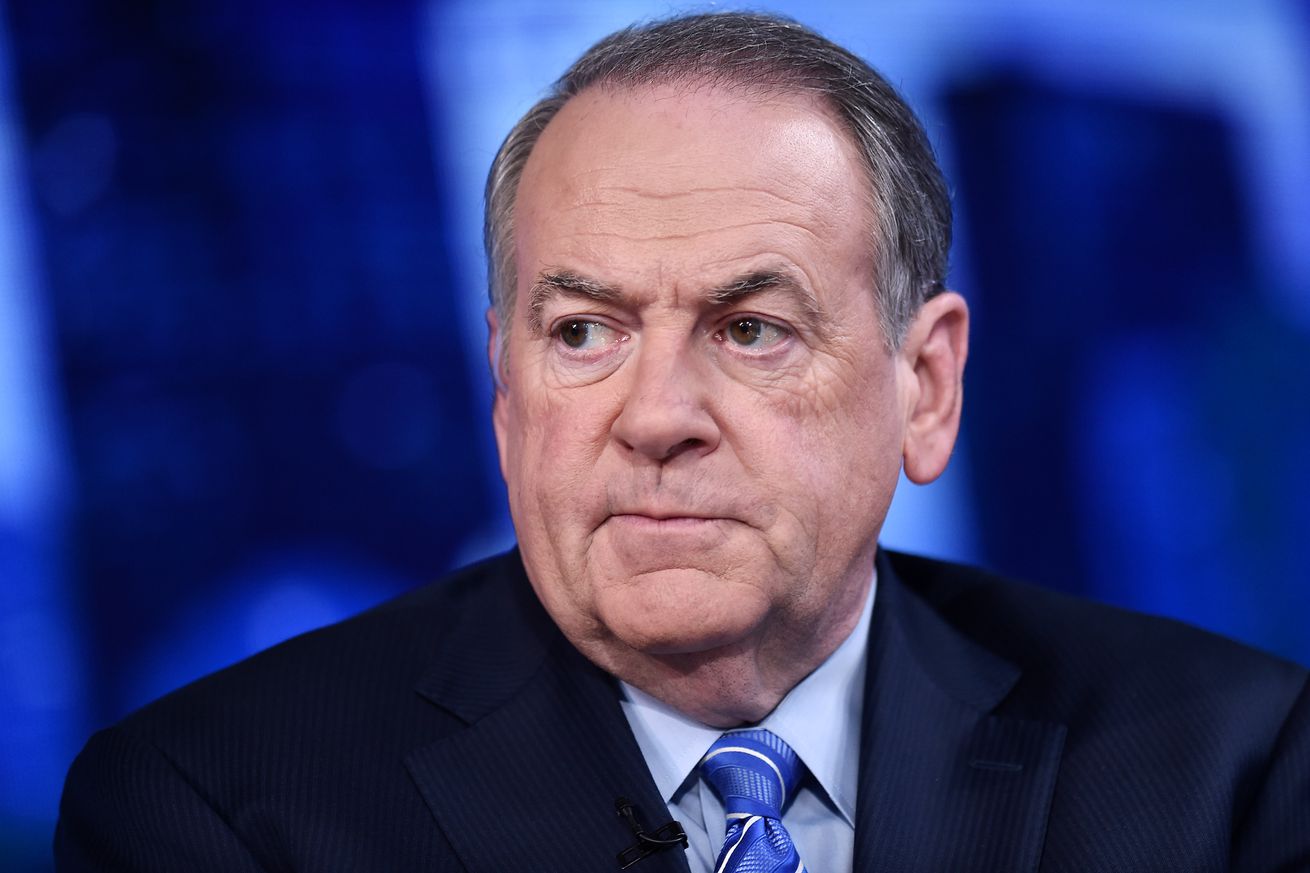
Former Arkansas Governor Mike Huckabee and Christian author Lysa TerKeurst are among a group of writers who have filed a lawsuit against Meta, Microsoft, and other companies for reportedly using their work without authorization to advance AI technology. The authors claim that their written material was unlawfully replicated and incorporated into AI algorithms for training. EleutherAI, an AI research group, and Bloomberg are also named as defendants in the lawsuit.
Products Worth Considering

DJI Osmo Pocket 3 Creator Combo Vlogging Camera with Mic 2, 1 CMOS, 4K/120fps, 3-Axis Stabilization, 128GB Card

Samsung 27-Inch Odyssey QD-OLED G8 4K 240Hz Gaming Monitor

DJI Osmo Pocket 3 Filter Bundle – Vlogging Camera with 1 CMOS Sensor and 4K/120fps
As an affiliate, we earn on qualifying purchases.
Authors join a growing list of those alleging copyright infringement by tech companies
This proposed class action suit is the latest example of authors accusing tech companies of using their work without permission to train generative AI models. In recent months, popular authors such as George R.R. Martin, Jodi Picoult, and Michael Chabon have also sued OpenAI for copyright infringement.
The case centers on a controversial dataset called “Books3”
The Huckabee case focuses on a dataset called “Books3,” which contains over 180,000 works used to train large language models. The dataset is part of a larger collection of data called the Pile, created by EleutherAI. According to the lawsuit, companies used the Pile to train their products without compensating the authors.
Microsoft, Meta, Bloomberg, and EleutherAI decline to comment
Microsoft, Meta, Bloomberg, and EleutherAI have not responded to requests for comment on the lawsuit. Microsoft declined to provide a statement for this story.
Debate over compensation for data providers in AI industry
The use of public data, including books, photographs, art, and music, to train AI models has sparked heated debate and legal action. As tools like ChatGPT and Stable Diffusion have become more accessible, questions surrounding how data providers should be compensated have arisen. Getty Images, for instance, sued the company behind AI art tool Stable Diffusion in January, alleging the unlawful copying of millions of copyrighted images for training purposes.