TL;DR

Get business pricing on tech for your team
- Business-only prices and quantity discounts
- Tax-exempt purchasing
- Multiple users, one account, clear invoices
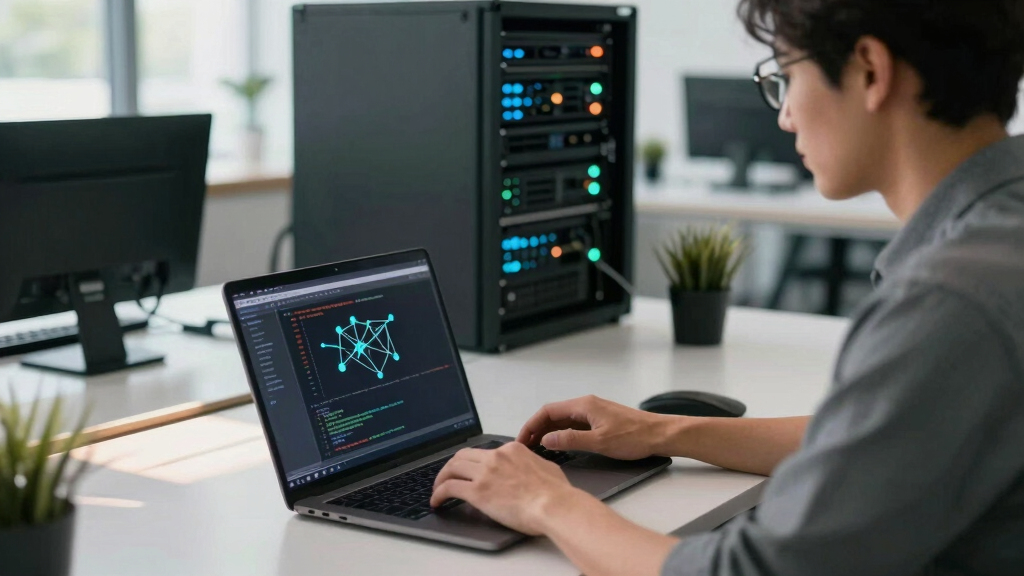
AWS has announced new infrastructure offerings, including NVIDIA GPU instances and high-bandwidth networking, designed to support large-scale foundation model training and inference. This development aims to enhance scalability and performance for ML researchers and engineers.
AWS has announced new infrastructure offerings, including advanced NVIDIA GPU instances, high-bandwidth networking, and scalable storage, aimed at supporting the training and inference of large foundation models at scale. This move addresses the growing demand for scalable, high-performance infrastructure in the AI community, enabling researchers and organizations to build and deploy more capable models.
The announcement details AWS’s expansion of its EC2 instance family, notably the P5 and P6 instances equipped with NVIDIA H100, H200, and Blackwell B200/B300 GPUs. These instances feature high peak tensor throughput, large HBM memory capacity, and fast interconnect bandwidth, critical for efficient distributed training of large models.
AWS also emphasizes the integration of these hardware capabilities with open-source software (OSS) stacks commonly used in foundation model workflows, such as PyTorch, JAX, and resource orchestration tools like Kubernetes. The infrastructure aims to support the entire model lifecycle—from pre-training to post-training and inference—by providing tightly coupled compute, networking, and storage resources.
Why It Matters
This development is significant because it provides the foundational hardware and infrastructure necessary for scaling foundation models more efficiently. As models grow larger and more complex, the need for high-performance computing, fast inter-node communication, and scalable storage becomes critical. AWS’s new offerings could accelerate research and deployment timelines, reduce infrastructure bottlenecks, and enable more organizations to participate in large-scale AI development.
As an affiliate, we earn on qualifying purchases.
Background
Scaling foundation models traditionally relied on increasing compute resources during pre-training, supported by empirical scaling laws. Recently, the focus has expanded to include post-training methods and test-time compute, requiring more integrated and scalable infrastructure. AWS’s announcement aligns with industry trends emphasizing the convergence of compute, networking, and storage for large-scale ML workflows, building on existing cloud offerings but now with specialized hardware and optimized configurations.
“Our new GPU instances and networking solutions are designed to meet the demanding needs of foundation model training and inference, enabling scalable, high-performance AI workflows.”
— AWS spokesperson
“The integration of NVIDIA’s latest GPUs with cloud infrastructure like AWS’s expands the possibilities for training state-of-the-art models at scale.”
— NVIDIA representative
high-performance GPU cloud server
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
What Remains Unclear
It is not yet clear how widely these new instances will be adopted by the AI community or how they compare in performance and cost-effectiveness to existing solutions. Details about specific deployment options, availability, and pricing are still emerging.
distributed storage for AI training
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
What’s Next
Next steps include AWS’s rollout of these instances to select regions, followed by broader availability. Monitoring tools and software integrations are expected to evolve to fully leverage the hardware capabilities. Further updates on performance benchmarks and case studies are anticipated in the coming months.
AWS EC2 GPU instances for machine learning
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
Key Questions
What specific hardware does AWS now offer for foundation model training?
AWS offers EC2 instances equipped with NVIDIA H100, H200, and Blackwell B200/B300 GPUs, featuring high tensor throughput, large HBM memory, and fast interconnects.
How does this infrastructure improve foundation model training?
The hardware provides higher compute capacity, faster communication, and scalable storage, reducing training time and enabling larger models to be trained efficiently.
When will these new instances be generally available?
AWS has announced the launch in October 2023, with broader availability expected in the upcoming months.
Will existing AWS customers need to modify their workflows to use these new instances?
Most workflows built on common OSS frameworks like PyTorch and Kubernetes should be compatible, but some adjustments may be needed to optimize performance for the new hardware.
Fall Picks
fall essentials
As an affiliate, we earn on qualifying purchases.