TL;DR

Get business pricing on tech for your team
- Business-only prices and quantity discounts
- Tax-exempt purchasing
- Multiple users, one account, clear invoices
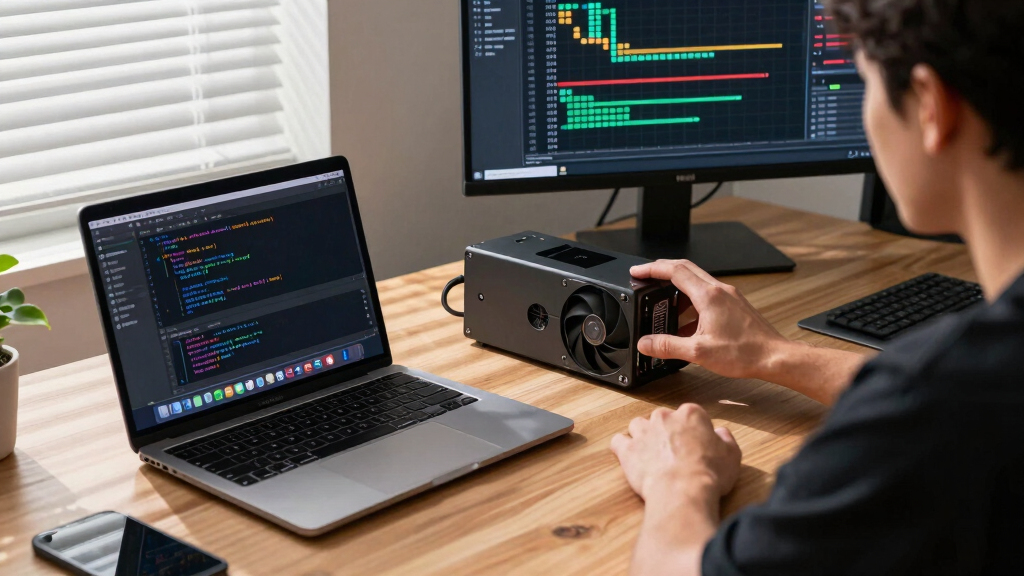
A developer rewrote and optimized matrix multiplication code in Swift to train a large language model on Apple Silicon. Initial performance was slow, but through targeted optimizations, they aim to reach Tflop/s levels, approaching the performance of C implementations.
A developer is actively working to optimize matrix multiplication in Swift to facilitate training large language models on Apple Silicon, with the goal of reaching Tflop/s performance levels.
The developer began by rewriting Andrej Karpathy’s llm.c, a plain C implementation of a GPT2-like model, in Swift. Initial attempts resulted in very slow performance, prompting a series of targeted optimizations. These included exploring different hardware units on Apple Silicon—CPU, SIMD, AMX, and GPU—and implementing multi-threaded code. The primary focus was on speeding up the core matrix multiplication kernel, which is the most computationally intensive part of training neural networks. The initial benchmarks showed a throughput of less than 1 Gflop/s, far below the Tflop/s potential of Apple Silicon. Through iterative improvements, the developer aims to push performance into the Tflop/s range, which would significantly reduce training times for large models.
Why It Matters
Achieving Tflop/s performance for matrix multiplication in Swift on Apple Silicon could enable more developers to train large language models directly on Mac hardware, reducing reliance on cloud-based solutions. It also provides insights into optimizing low-level mathematical operations in Swift, potentially influencing future machine learning workflows on Apple devices.
Products Worth Considering

Apple iPad 11-inch with A16 Chip, 512GB, Wi-Fi 6, and Apple Pencil (USB-C) — Blue

Apple iPad Pro 12.9-inch (2017), 512GB Wi-Fi, Space Gray

Apple MacBook Air 13.6-inch Laptop with M5 Chip, 16GB Memory, 512GB SSD, Sky Blue
As an affiliate, we earn on qualifying purchases.
Background
Two years ago, the developer revisited an old neural network project, motivated by the lack of native ML training in Swift on Macs. Inspired by Karpathy’s llm.c, they rewrote the code in Swift, initially with poor performance. The challenge was to optimize matrix multiplication, which dominates the computational workload in training neural networks. Apple Silicon’s architecture offers high FLOP counts, but extracting that performance in Swift requires careful low-level optimization. Previous frameworks like Metal and Accelerate are highly optimized, but the developer aims to understand and improve performance at a more fundamental level, writing kernels from scratch.
“The initial Swift implementation was really super slow, but optimization is a constant process: there’s always something more you can try.”
— Developer
“My goal is to push matrix multiplication performance into the Tflop/s range on Apple Silicon, making training faster and more accessible.”
— Developer
What Remains Unclear
It is not yet clear how close the developer will get to Tflop/s performance levels in Swift, or how scalable these optimizations are across different model sizes and hardware configurations. The effectiveness of future Metal-based kernels remains to be tested, and the impact of multi-threading and hardware-specific features is still being evaluated.
What’s Next
The developer plans to continue refining their matrix multiplication kernels, incorporating Metal GPU acceleration, and benchmarking performance improvements. They aim to reach or surpass Tflop/s levels in the near future, with potential publication of detailed performance metrics and code updates.
Key Questions
Why is optimizing matrix multiplication important for training large language models?
Matrix multiplication is the core computational task in neural network training, accounting for most floating-point operations. Faster matrix multiplication directly reduces training time and resource consumption.
What hardware units on Apple Silicon are being utilized for optimization?
The developer is exploring CPU, SIMD, AMX, and GPU units to maximize performance and leverage the full computational capacity of Apple Silicon.
Can these optimizations be applied to other machine learning workloads?
Yes, improvements in low-level matrix kernels can benefit various ML tasks that rely on heavy linear algebra, although specific tuning may be required for different models.
Will the developer release the optimized code or benchmarks?
The developer has not confirmed release plans but intends to continue benchmarking and refining, which may lead to sharing code or performance data in future updates.